U-Codec: Neural Speech Codec under Extreme Temporal Compression for Fast High-fidelity Speech Generation
· Code ·
We propose U-Codec, an Ultra low frame-rate neural speech Codec that achieves high-fidelity reconstruction and fast speech generation at a frame-rate of 5Hz (5 frames per second). Extreme temporal compression typically leads to severe intelligibility and spectral detail loss. We overcome this by introducing a Transformer-based inter-frame long-term dependency module and systematically exploring residual vector quantization (RVQ) depth and codebook size to identify optimal configurations. Moreover, we apply U-Codec to a large language model (LLM)-based auto-regressive TTS model, which leverages global and local hierarchical architecture to effectively capture dependencies across multi-layer tokens. Experiments demonstrate that U-Codec improves LLM-based TTS inference speed by 3$\times$ over high-frame-rate codecs while maintaining similarity and naturalness. These results validate the feasibility of using 5Hz discrete tokens for fast and high-fidelity speech synthesis.
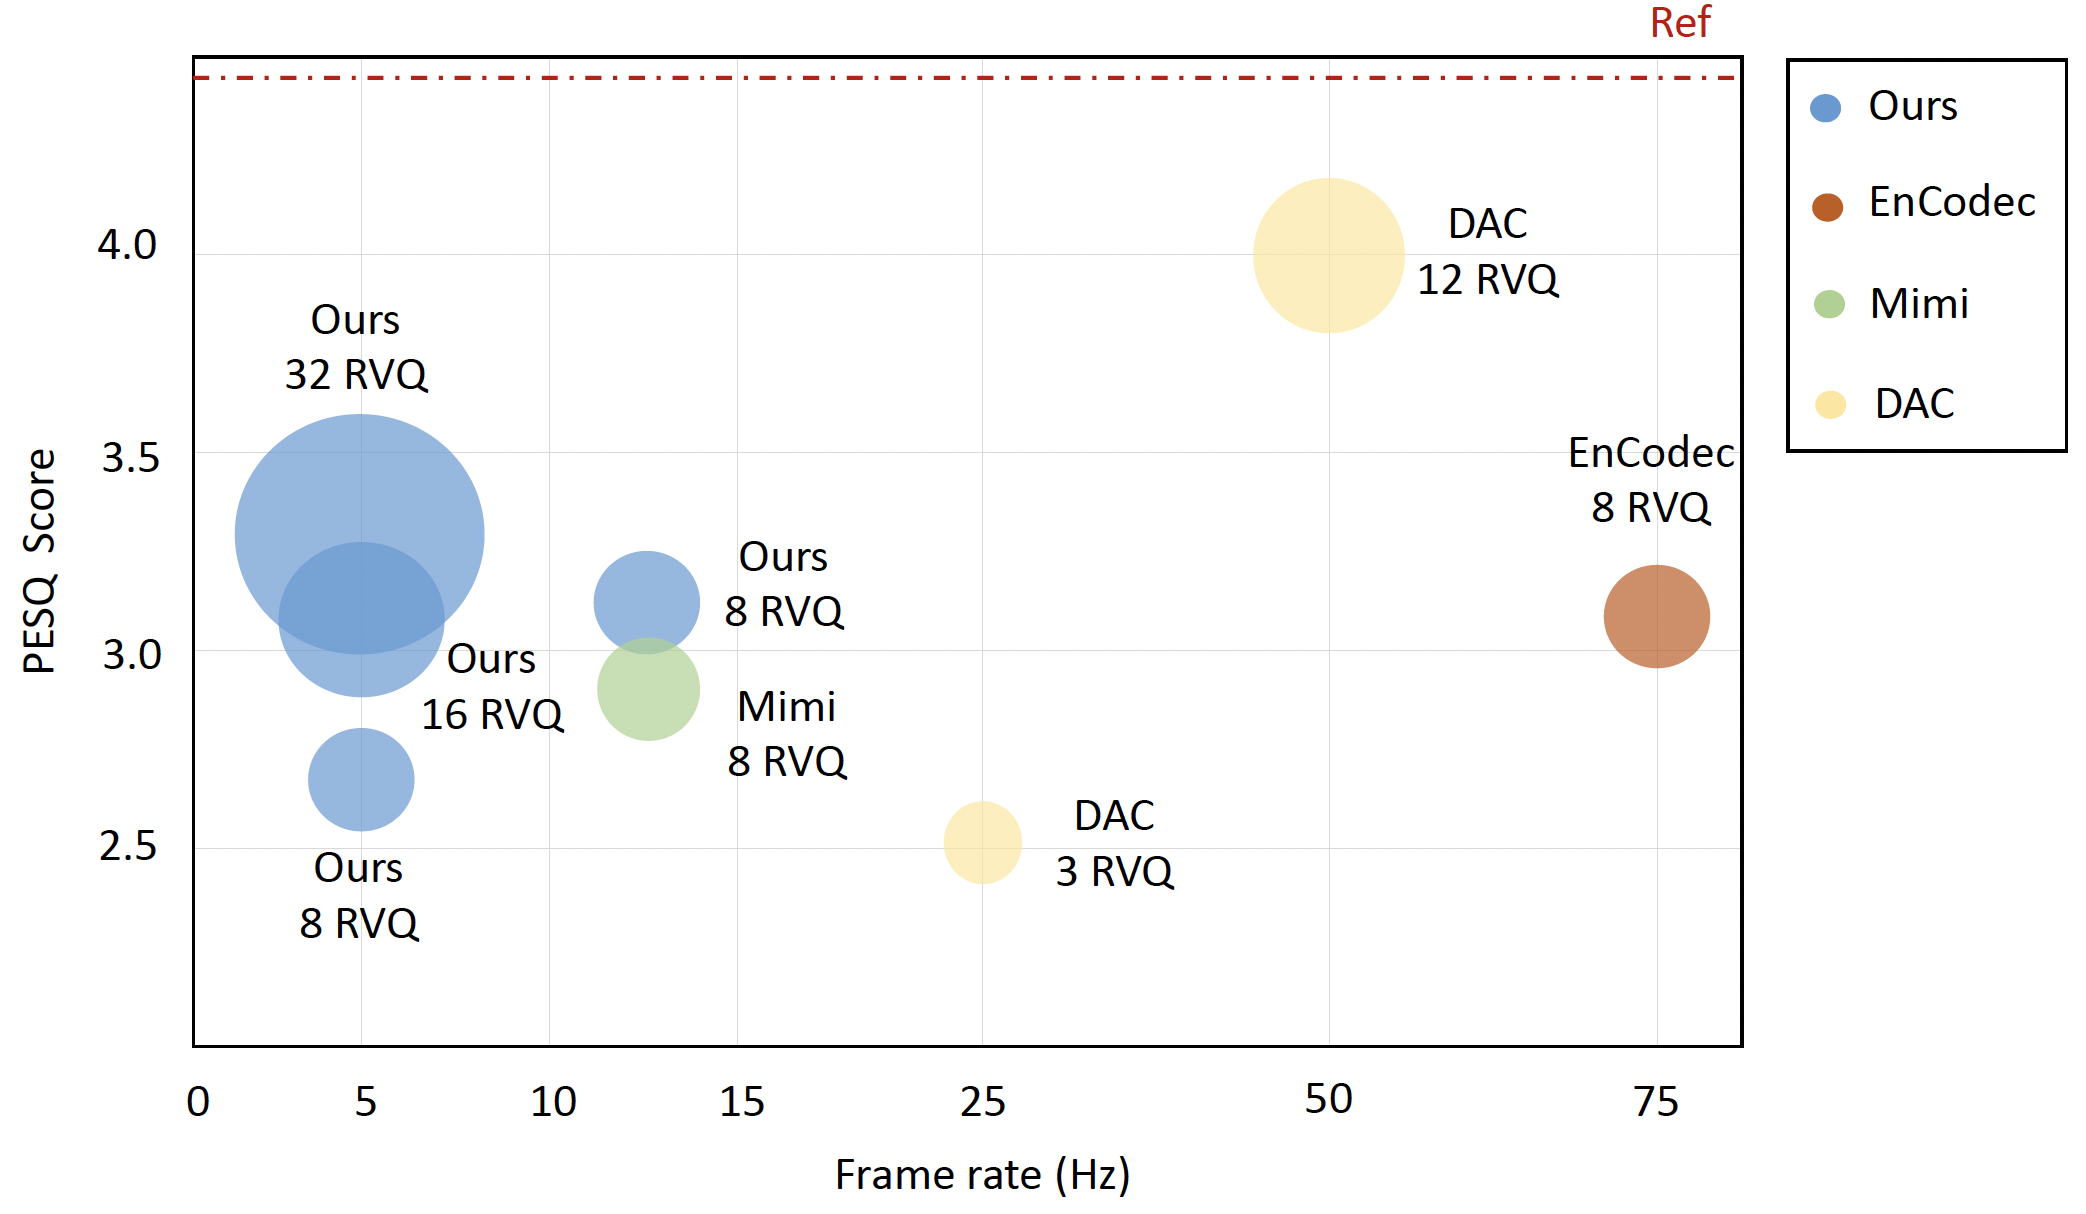
Fig.1 Preliminary experiments on varying the frame rate and RVQ depth of different codecs. Bubble size indicates the number of RVQ layers. Our method achieves competitive PESQ performance under ultra low frame rates (5–12.5Hz), demonstrating the effectiveness of the tokenizer with multi-layer RVQ. EnCodec, Mimi, and DAC operate at higher frame rates.
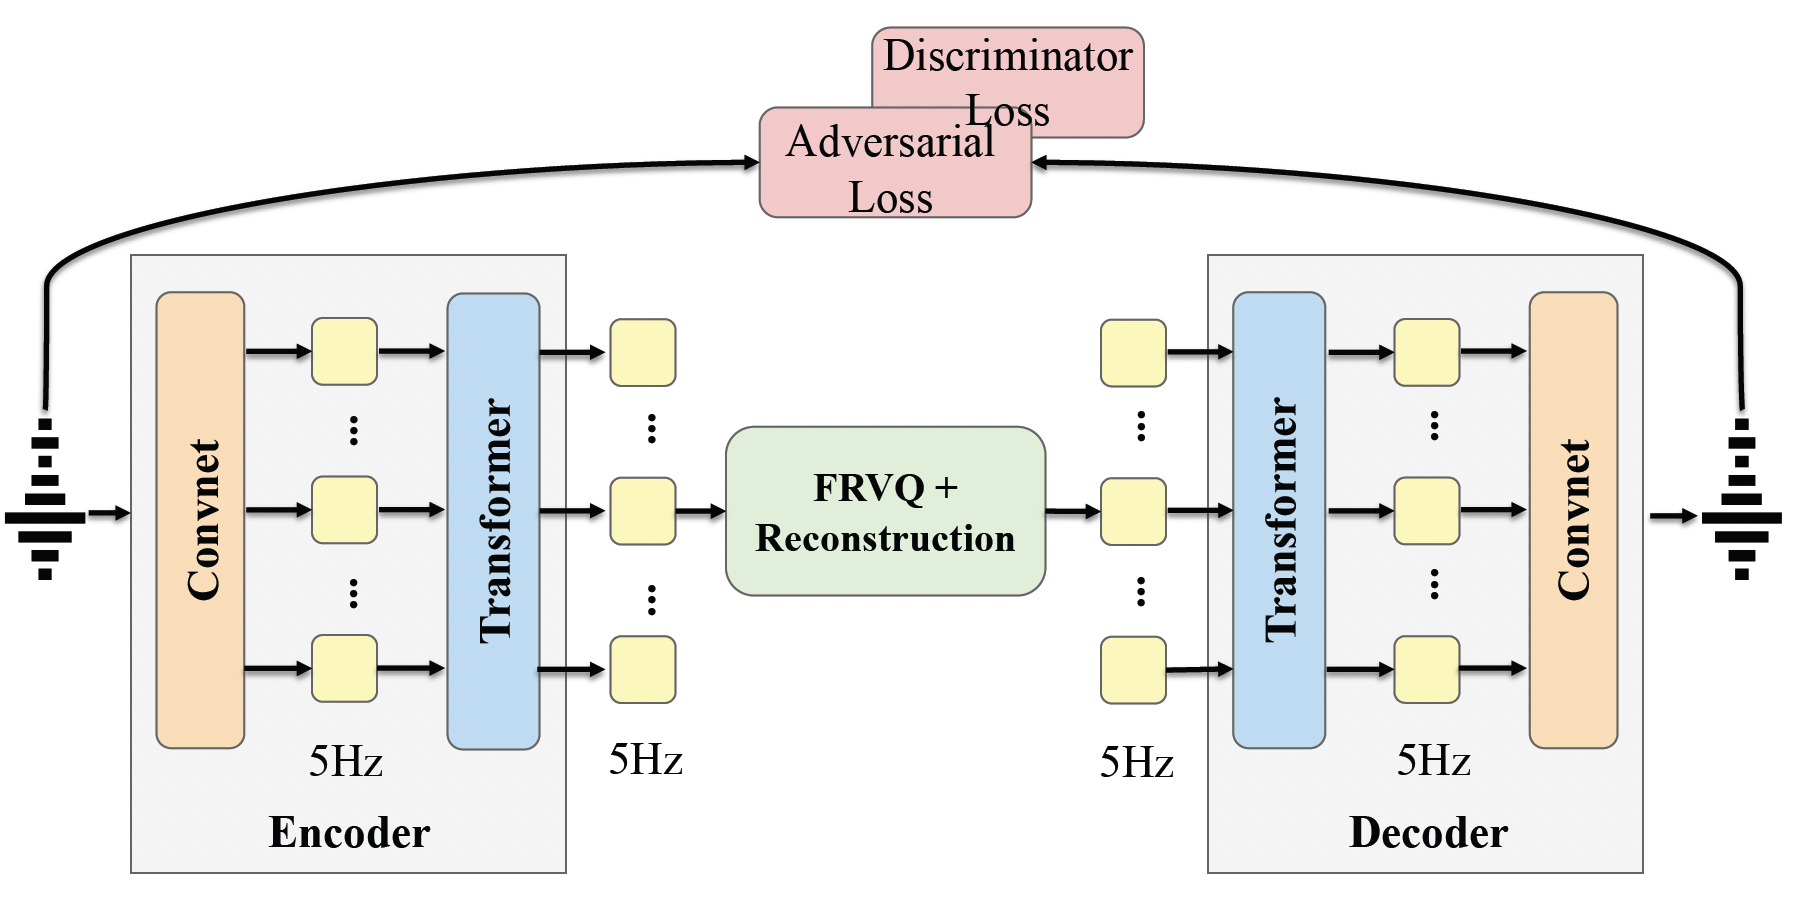
Fig.2 Architecture and training of our U-Codec at 5Hz. The encoder (left) consists of convolutional layers followed by a Transformer to capture long-term dependencies. Latent features are quantized through factorized residual vector quantization (FRVQ) and optimized for high-fidelity reconstruction. The decoder (right) mirrors the encoder to synthesize the output waveform.
Open-Source
We open-source U-Codec at 12.5Hz and 5Hz, along with inference and training codes, and are preparing to release U-Codec-based TTS (based on CodecFormer network). These will provide diverse configurations and multiple frame rates to support broader exploration of speech language modeling.
Low Frame-rate Speech Reconstruction Quality
Neural speech codecs often degrade at low frame rates. Here, we showcase U-Codec’s superior reconstruction quality over other advanced codecs.
| Ground-Truth | U-Codec 5Hz 32RVQ | U-Codec 5Hz 16RVQ | Mimi 12.5Hz 8RVQ | WavTokenizer-large 75Hz 1RVQ | DAC 75Hz 8RVQ | Encodec 75Hz 8RVQ | SpeechTokenizer 50Hz 8RVQ | DualCodec 12.5Hz 6RVQ |
|---|---|---|---|---|---|---|---|---|
| Lang: EN | ||||||||
| Lang: EN | ||||||||
| Lang: EN | ||||||||
| Lang: EN |
Text-to-Speech Performance
Compared to the baseline of UniAudio, our U-Codec achieves higher TTS quality at 5Hz, with better timbre similarity, lower word error rate, and more natural prosody.
| Text | Reference Audio | U-Codec-8RVQ-c16384 5Hz | U-Codec-16RVQ-c4096 5Hz | U-Codec-32RVQ-c256 5Hz | U-Codec-100RVQ-c4 5Hz | U-Codec-8RVQ-c1024 12.5Hz | UniAudio (reproduced) 25Hz |
|---|---|---|---|---|---|---|---|
| FORTHWITH ALL RAN TO THE OPENING OF THE TENT TO SEE WHAT MIGHT BE AMISS BUT MASTER WILL WHO PEEPED OUT FIRST NEEDED NO MORE THAN ONE GLANCE. | |||||||
| SOMEONE ELSE TOLD A STORY NOT PARTICULARLY EFFECTIVE WHICH I SAW HE WAS NOT FOLLOWING. | |||||||
| THEN DEAR SAID MISSUS WHITNEY YOU MUST BE KINDER TO HER THAN EVER THINK WHAT IT WOULD BE FOR ONE OF YOU TO BE AWAY FROM HOME EVEN AMONG FRIENDS. | |||||||
| WE ARE LOSING TIME AND THE FACT IS I HAVE NOT COME ALL THIS WAY TO TAKE A LITTLE SAIL UPON A POND ON A RAFT. |
Citation
@inproceedings{U-Codec,
  title     = {U-Codec: Neural Speech Codec under Extreme Temporal Compression for Fast
High-fidelity Speech Generation},
  author    = {Anonymous authors},
  booktitle = {arXiv},·
  year      = {2026}
}